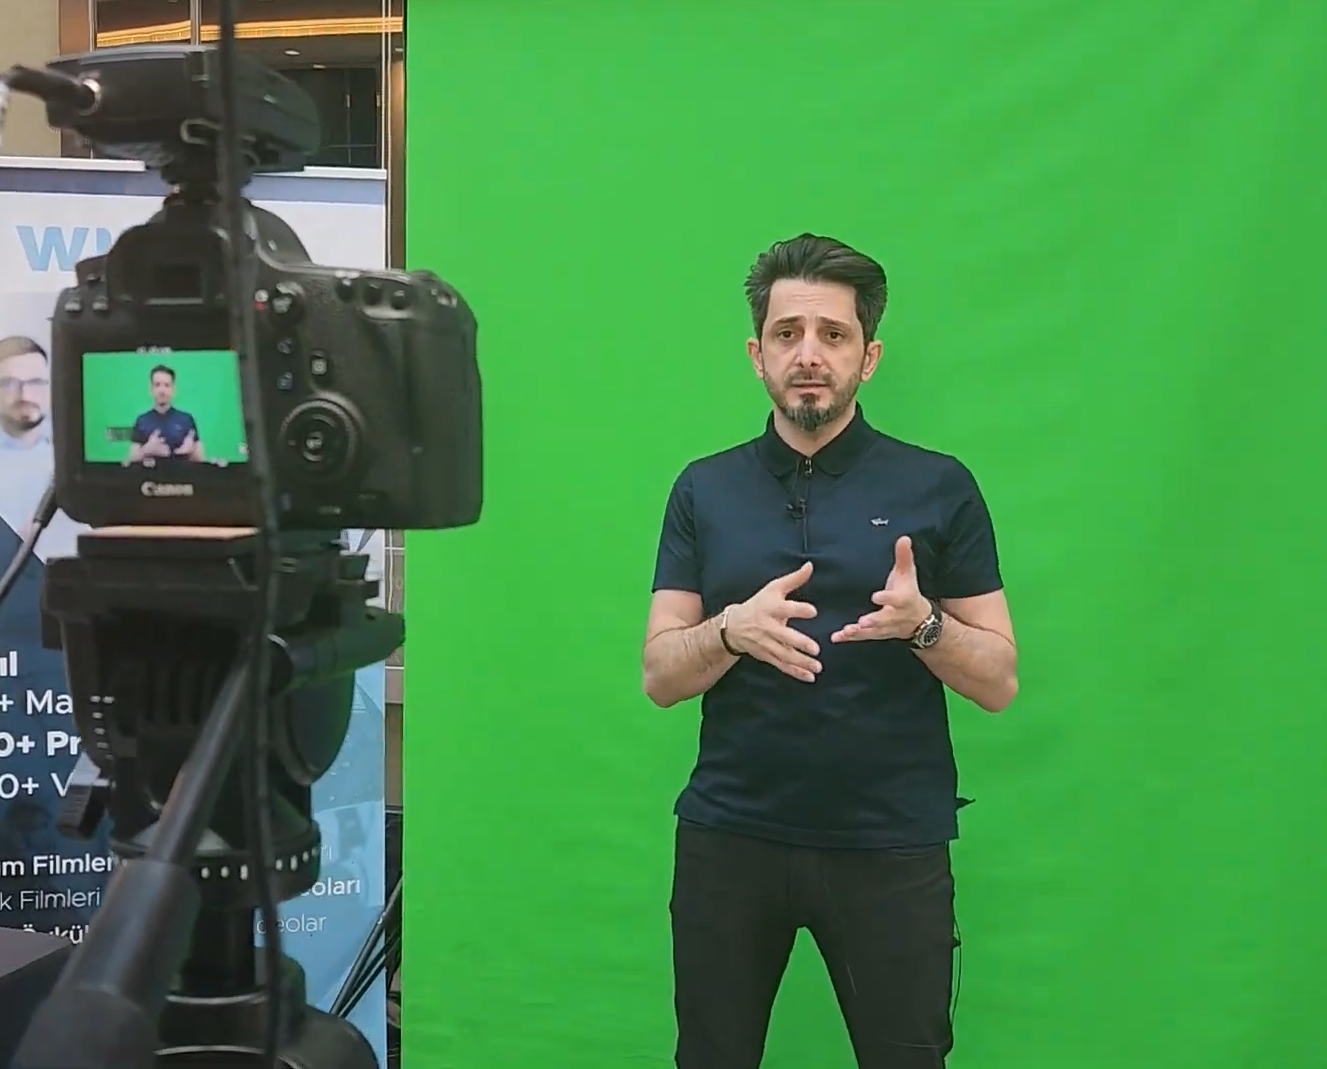
Mehmet Taşan, Team Leader for Data and Artificial Intelligence Applications at Softtech, discussed the opportunities and challenges associated with the use of Large Language Models (LLMs) with Wise TV.
We utilize Large Language Models (LLMs) when operating our networks. These models rely on massive training datasets; because they are trained on such vast amounts of data, they can sometimes absorb nonsensical information or inherent biases. LLMs also come with certain downsides, such as “hallucination.” Hallucination refers to instances where the model generates answers entirely of its own making, unrelated to the actual question asked. When the assistant receives a query, we always subject the output to a two-stage process; we do not simply relay the answer directly to the user or customer—we always put the generated response through a verification process. Then there is the aspect of security attacks. Just as we used to subject applications like internet and mobile banking to penetration testing before deployment, in today’s landscape, we put these assistants—or software “agents”—through “red teaming” penetration tests. We generally outsource this task to specialized third-party firms, as they can test the assistants’ responses under various conditions. Malicious users can sometimes compromise the programs we use. To prevent these attacks, we employ software layers that act as security mechanisms. We leverage AI models for this purpose as well; however, rather than using LLMs, we rely on models trained via traditional machine learning or deep learning techniques to thwart these malicious attacks.
The Power and Limitations of Large Language Models
Large language models are considered one of today’s most influential artificial intelligence tools. Trained on massive datasets, these models possess the capacity to generate human-like text. However, alongside their capabilities, they also have certain limitations. The diversity and quality of the data used during training can directly impact model performance. Consequently, there are several factors to consider when using large language models.
Bias and Nonsensical Data
Since large language models are trained on vast datasets, they may occasionally encounter biased or nonsensical data. This can lead to unexpected results in the models’ outputs. Bias can cause a model to produce skewed results regarding a specific topic or group. To prevent such issues, training data must be carefully selected and curated.
The Hallucination Problem
Hallucination is one of the major drawbacks of large language models. When responding to user queries, a model may sometimes generate answers that are entirely fabricated. This can negatively affect the user experience and lead to misinformation. Therefore, model outputs should be carefully examined and verified.
Two-Layer Verification Process
A two-layer verification process is implemented to ensure the accuracy of responses generated by large language models. This process ensures that the model’s responses undergo a verification stage before being delivered to the user. This prevents incorrect or misleading information from reaching the user. Cybersecurity and Penetration Testing
Penetration testing is crucial for ensuring the security of AI-based systems. Just as applications like internet and mobile banking undergo such testing, AI assistants must also be subjected to penetration tests. These tests are used to identify system vulnerabilities and implement safeguards against malicious attacks.
Third-Party Security Firms
Penetration tests are typically conducted by third-party firms specializing in this field. These firms perform various tests and analyses to ensure the security of AI systems, thereby enhancing system security and protecting user data.
Security via Machine Learning and Deep Learning
In addition to large language models, machine learning and deep learning techniques are also employed in the realm of security. These techniques can be effectively used to detect and prevent malicious attacks. AI-based security systems are continuously updated to become more resilient against emerging threats.
Summary
Large language models are considered a revolutionary development in the world of artificial intelligence. However, there are several factors to consider when using these models. Issues such as bias, hallucinations, and security concerns can impact the effectiveness of large language models. Therefore, model outputs must be carefully examined and verified. Furthermore, the security of AI systems must be ensured through the implementation of cybersecurity measures. Third-party firms and machine learning techniques play a vital role in this process.
About the Wise
Similar Videos from this Wise
How do chatbots learn to defend against attacks?
Mehmet Taşan, Team Leader for Data and Artificial Intelligence Applications at Softtech, explained on Wise TV how AI-powered...